

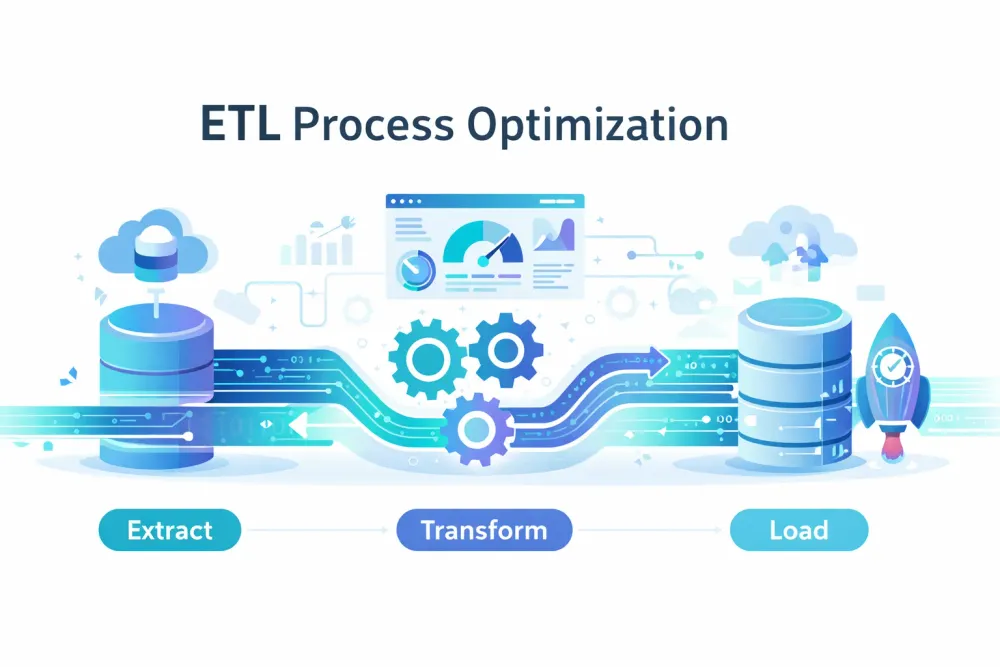
ETL process optimization is the work of making data pipelines faster, cheaper to run, and less likely to break — without sacrificing the accuracy of the data flowing through them.
Data teams reportedly spend 44% of their time on data preparation and integration work, according to Anaconda’s State of Data Science report, and that share only grows when pipelines are poorly tuned. The good news is that most of the wasted time traces back to a small set of recurring problems, each with a well-understood fix.
What ETL Process Optimization Actually Involves
At its core, ETL process optimization means improving how data is extracted, transformed, and loaded so that each stage runs faster and consumes fewer resources without compromising data quality. It spans three distinct areas of work rather than a single fix.
Technical tuning covers the pipeline code itself: parallelizing tasks, rewriting slow queries, partitioning large tables, and managing indexes. Architectural decisions sit one level up, covering choices like ETL versus ELT patterns, cloud versus self-managed infrastructure, and how staging layers are designed to contain failures before they spread.
Operational practices round out the picture — monitoring, alerting, scheduling, and benchmarking pipeline performance against defined service-level agreements over time. Treating optimization as a combination of all three, rather than just faster code, is what separates a pipeline that stays fast from one that degrades again within a few months.
Measure Before You Touch Anything

Optimization without a baseline is just guessing. Before changing a pipeline, log its current performance across a few key metrics so you have something concrete to compare against later. Pipeline latency, the time between a source change and its availability in the target system, should ideally sit under 15 minutes for anything close to real-time reporting.
Throughput, error rate, and resource utilization matter just as much. A healthy pipeline typically runs at 70–80% sustained CPU and memory usage rather than spiking to 100%, and error rates should stay below roughly 0.1% of processed records. Data freshness and recovery time round out the metrics worth tracking on every run.
Storing these numbers in a time-series system, whether that’s a dedicated monitoring tool or simply a logging table in your warehouse, turns optimization into a measurable process instead of a one-off guess. Without that history, it’s impossible to know whether a change actually helped.
Extracting Only What Changed
Full-table extraction is one of the most common sources of wasted pipeline time, and switching to incremental loading is usually the single highest-impact change available. Rather than pulling every row on every run, incremental extraction filters for records that changed since the last successful run, dramatically cutting both processing time and data transferred.
Timestamp-based extraction works well when a source table has a reliable “last updated” column, using that value as a high-water mark for each run. It has one blind spot, though: deleted records never show up in a filter based on update time, since the row simply disappears rather than getting flagged as changed.
Change data capture, or CDC, solves that gap by reading a database’s transaction log directly rather than querying the table itself. This captures inserts, updates, and deletes as a continuous stream and adds minimal load to the source system, since it reads logs the database is already writing.
Transforming Data Without Wasting Compute
Transformation is typically where the bulk of a pipeline’s compute gets consumed, and the fix is rarely about adding more hardware. Row-by-row processing is one of the most common performance bottlenecks in transformation logic, and replacing it with set-based operations that process an entire column or table at once can deliver 10 to 100 times the speed.
A related shift is pushing transformation work into the data warehouse itself rather than handling it in a separate application, an approach generally known as the ELT pattern. Because modern cloud warehouses can parallelize queries and optimize execution plans automatically, this pushdown approach typically delivers 2 to 5 times faster performance.
Two smaller habits round out efficient transformation: caching lookups against slowly changing reference data instead of re-querying it on every batch, and filtering data as early in the pipeline as possible. Every row and column eliminated before the heavy transformation logic runs reduces the compute required for every step that follows.
Loading Data Efficiently at Scale
Loading transformed data into its final destination introduces its own bottlenecks, mainly around write contention and index overhead. Standard row-by-row INSERT statements process one transaction per row, while bulk loading commands can load the same data 5 to 10 times faster by bypassing that per-row overhead entirely.
Partitioning large tables by a column like order date also pays off on both sides of a pipeline. Writes only need to touch the relevant partition instead of locking the whole table, and reads that filter on the same column scan a fraction of the data. For teams running frequent daily loads, this keeps new writes from colliding with analysts querying historical data.
Indexes speed up reads but slow down every write, since the database has to update each one on every insert. For large batch loads, a common approach is to drop non-essential indexes before loading and rebuild them afterward — a pattern that can cut load time by 30–50% on multi-million-row batches.
Parallel Processing and Building in Recovery
Splitting a large dataset into independent segments and processing them concurrently is one of the most scalable optimization techniques available, since it multiplies throughput rather than just tuning a single query.
Range partitioning by date, hash partitioning for evenly distributing skewed data, and list partitioning by discrete values like region are the three most common strategies, each suited to a different data shape.
Parallelization only works when tasks are genuinely independent, though, so a running total that depends on the prior date’s output can’t simply be split across workers without redesigning the logic first.
A three-layer structure works well here — a raw landing layer that holds data exactly as extracted, a staging layer where validation and transformation happen, and a production layer that only receives data once it passes every check.
Orchestration, Monitoring, and Data Quality Checks
Moving beyond cron jobs to a proper orchestrator models a pipeline as a directed acyclic graph, where each task only starts once its dependencies finish successfully. This structure brings automatic retries, dependency tracking, and historical run logs that a scattered set of cron jobs simply can’t provide on its own.
Scheduling choices matter too. Running large historical loads during off-peak hours typically cuts runtime by 30–50% due to reduced contention, while event-driven triggers eliminate the delay and waste of running on a fixed schedule when nothing has actually changed.
Data quality checks belong inside this same workflow rather than bolted on afterward — validating schema and required fields right after extraction, checking business rules like referential integrity after transformation, and comparing record counts between staging and production after loading.
None of this replaces monitoring, but it feeds it. Tracking execution time per stage, row counts at each checkpoint, resource consumption, and error types by category turns a pipeline failure from a mystery into something you can diagnose in minutes rather than hours. A pipeline without this visibility tends to fail silently long before anyone notices.
Where AI Is Changing ETL Optimization
AI is increasingly taking over the more repetitive parts of pipeline tuning rather than replacing the discipline itself. Automated query plan analysis can review execution plans and suggest index changes or query rewrites that would otherwise require a specialist’s manual review.
Anomaly detection is another area where AI adds real value, flagging unusual execution times or unexpected row count drops before they escalate into full incidents.
For teams without dedicated data engineers, natural-language-to-SQL tools are lowering the barrier to writing efficient queries in the first place, turning a plain-language question into something closer to an optimized query than a first draft would be.
Even with these gains, human oversight remains part of the process. AI can flag a schema change or suggest a rewrite, but deciding whether a breaking change should halt a pipeline, or whether an anomaly reflects a real business shift rather than a bug, still requires someone who understands the data.
What These Optimizations Typically Deliver
The numbers vary by workload, but the pattern across published benchmarks is consistent. Incremental loading typically cuts processing time and data transfer by 60–90% compared to a full refresh, while replacing row-by-row logic with set-based SQL routinely delivers 10 to 100 times faster transformations.
Bulk loading operations tend to run 5 to 10 times faster than row-by-row inserts, and parallel processing across eight workers commonly delivers a 5 to 7 times throughput increase.
Combined rather than applied in isolation, these techniques often take pipelines that used to run for four to six hours down to under an hour. Teams that tackle incremental loading and parallel processing together tend to see the largest gains, since the two changes address volume and concurrency at the same time rather than solving just one bottleneck.
Keeping Pipelines Fast Over Time
ETL optimization isn’t a project with a finish line — data volumes grow and source systems change, so a pipeline that’s fast today can slow down within months without anyone touching the code.
A monthly review of latency, throughput, and error rate against your original baseline catches degradation before it becomes an SLA breach, and a periodic test against ten times the current data volume exposes bottlenecks before they show up in production.
Documenting every optimization change, along with its before-and-after numbers, builds institutional knowledge that keeps a team from quietly drifting back to slower patterns after the person who fixed it moves on. Treated this way, optimization becomes a habit built into how the pipeline is run rather than a one-time cleanup project.
FAQs
How do you optimize an ETL process?
Focus on incremental extraction, set-based transformations instead of row-by-row logic.
What are the main stages of an ETL process?
The core stages are extraction, transformation, and loading, though many teams now break this into five steps.
What is ETL processing, in simple terms?
It’s the workflow of pulling data from various sources, reshaping and cleaning it into a consistent format.
Will AI eventually replace ETL pipelines entirely?
Not entirely — AI is automating specific tasks like schema mapping and anomaly detection.
What’s the fastest way to reduce ETL runtime?
Switching from full-table extraction to incremental loading usually delivers the biggest single improvement.
